

Date:
Article 1 of 6 in New Lamps for Old, a series on bringing AI into regulated financial processes.
Alyona Bulda and Marina Kudriavtceva, Exactpro
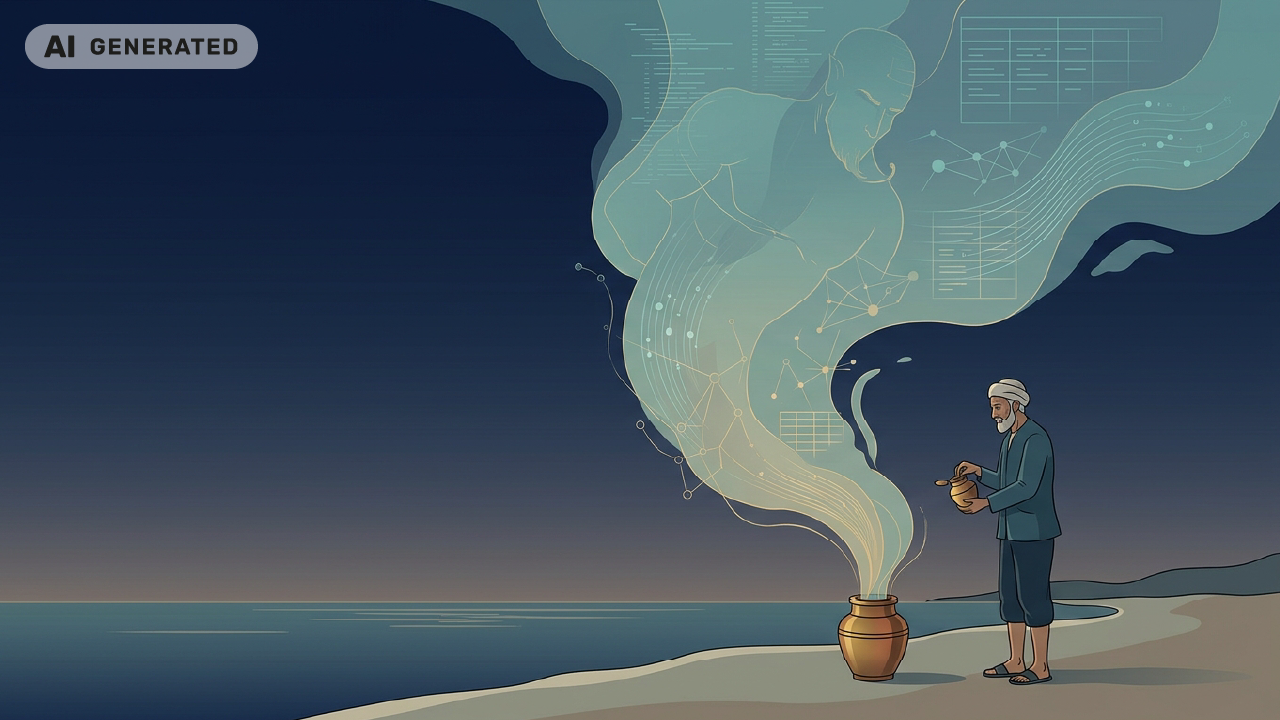
Sealed in a brass jar at the bottom of the sea, an Ifrit vows first to make his rescuer rich, then to grant three wishes – and finally, after four hundred years, to kill whoever sets him free. When a poor fisherman opens the jar, he survives by doubting the Ifrit's claim that so vast a being ever fit inside it:
“How didst thou fit into this bottle which would not hold thy hand; no, nor even thy foot, and how came it to be large enough to contain the whole of thee?” [...]
“Nay! I will never believe it until I see thee inside with my own eyes.”
“The Fisherman and the Jinni”, in The Book of the Thousand Nights and a Night, trans. Richard F. Burton, vol. I (1885)
The jar is open
Financial firms are now standing where the fisherman stood: the jar is open, and what comes out has to be put to work. According to a September 2026 A-Team Group survey (commissioned by LSEG Data & Analytics) of 200 senior AI decision-makers at buy-side and sell-side firms in the US, UK and Canada, institutions are no longer asking whether to invest in AI, but how to move from experiment to operation. Its sharpest finding: firms that put data readiness first are scaling, while those that led with model capability are still piloting (A-Team Group, LSEG, 2026).
The wider evidence points the same way. The Cambridge Centre for Alternative Finance's 2026 global survey, run with the BIS, IMF and World Economic Forum among others, finds that 81% of financial firms are adopting AI at some level, yet only 14% see it as transformational to their strategy. Four of the top five use cases are back-office functions, software engineering is the most mature AI application, and 55% of firms find the value of AI hard to measure (CCAF, 2026). Testing shows the same gap between adoption and scale. The World Quality Report finds 89% of organisations piloting or deploying generative AI in quality engineering, with test case design and requirements refinement now leading adoption, yet only 15% have reached enterprise scale (World Quality Report, 2025). Google’s DORA research describes AI as an amplifier: it magnifies the strengths of high-performing teams and the dysfunctions of struggling ones (Google Cloud, 2025).
The supply side deserves the same attention. A BIS Bulletin published in October 2026 shows how tightly the AI industry is knotted together. Between 2021 and 2025, 55.2% of the investment flowing into AI firms came from other AI firms, and nearly half of the value of AI-to-AI deals involved companies that were also each other's suppliers or customers. The authors warn that these circular ties make the sector more opaque and more likely to pass on shocks (Frost et al, 2026). For a financial firm, every AI use case is also a new dependency on a small, closely connected group of providers. The Bank of England and FCA’s latest survey shows this is already happening in the UK: third-party systems now make up 39% of the AI in use, and more than half of the highest-materiality systems (Bank of England, FCA, 2026).
All of this leads to the same point: the decision that matters most is not which model to use, but where to put it, and how to check what it produces.
The wish list
Most firms begin their AI journey the way the fisherman began his day: with a net cast wide and little idea of what will come up. A steering committee asks every department for use cases, and the result is a long wish list – summarise every report, automate every reconciliation, write every test – and a portfolio of pilots that each look promising in a demo.
A year later, only a few have reached production. Fewer still have a clear owner, an agreed measure of success, or sign-off from risk and compliance. Like the Ifrit’s promises, a wish list that’s too long turns from opportunity into liability. The technology rarely fails on its own. What fails is the choice of where to place it. And the true cost of an AI use case is not only the model, but also the testing, monitoring and ownership that accompany it before it can go into production, and beyond.
The problem is not ambition. It is that a wish list is ranked by how impressive a use case sounds, not by how well it fits the process it lands in. In the regulated financial infrastructure, the first question should not be "What could AI do here?" but "What happens when it gets this wrong, and who will notice?".
Five questions that should be asked before the jar gets opened
A process is a good first home for AI when the answers to five questions point the same way. None is about the model, and all are about the process around it.
- Will an error be visible? If a wrong output is caught downstream – by a reconciliation or a four-eyes check – the process has a safety net. If a wrong output flows silently into a ledger, a report or a trading decision, it does not.
- Can it be undone? A draft email can be rewritten. A settled trade, a filed regulatory report or a wrongly rejected client cannot easily be unwound. The cost of an error is the damage it does before anyone notices.
- Is there a ground truth? Known correct outcomes – matched breaks, resolved queries, labelled alerts – let you test the system before it goes live and keep testing it after. Processes where "correct" is a matter of opinion make that much harder.
- Is the work repetitive, but too varied for rules? AI earns its place where volume is high and each case differs just enough that rule-based automation keeps breaking. Low volume rarely repays the effort. Fully predictable work is better served by conventional automation.
- Who owns the outcome? Every AI-assisted decision still needs a named person accountable for it. If no one can say who signs off – or the honest answer is "the model" – the process is not ready.
The pattern is simple to state: start where errors are cheap, visible and measurable, and where someone already owns the result. That is rarely where the most exciting demos are.
Where AI fits today
Applied to an exchange, a CCP or a bank, the five questions favour a recognisable group of candidates. What they share is a division of labour: the AI proposes, and a person or an existing control disposes.
- Break and exception investigation. Reconciliation and post-trade teams spend much of their day working out why two records disagree. AI can propose the likely cause and the next step, drawing on how similar breaks were resolved before. The analyst still resolves the break, and past resolutions provide the ground truth.
- Surveillance alert triage. Surveillance teams face large volumes of alerts, most of them false positives. AI can rank and summarise alerts so analysts look at the riskiest first. The rules engine stays in place as the baseline: AI changes the order of the queue, not what enters it.
- Document extraction in onboarding and operations. Pulling data from prospectuses, legal agreements and client documents is repetitive, laborious and checkable against the source. Software testing. Generating test scenarios from specifications and rulebooks, analysing test results and spotting gaps in coverage all play to AI's strengths. Feedback is fast and failures are visible, but a tester still reviews what each generated test actually validates.
- Internal knowledge search. Answering staff questions from rulebooks, operating procedures and technical documentation, with every answer linked to its source, saves time without taking any decision out of human hands.
None of these replaces a function. Each removes friction from work that people already do and already own.
Samir Patki, who heads testing and risk IT at Cboe Clear Europe, describes what this looks like in practice:
“ “AI has definitely been a great assistant: helping to write code for automated tests, generating test data for volume and capacity testing, and identifying traceability and coverage gaps. All of this is done by providing very clear context and approved documentation. In QA, you can't replace the human in the loop: all the outputs must be reviewed and not used as is. The process is still evolving; we are still learning and improving along the way. This is a journey.
Director, Head of QA / Risk IT, Cboe Clear Europe
Where to hold back
John Greenan, whose financial industry career has spanned multiple exchange technology architect roles, explains why trading venues draw the line where they do:
“ “Regulated trading venues prize determinism, low-latency and low-jitter. Vast amounts of effort are expended on these goals. Where AI can assist then it has a place in the process. For markets with capability for 1:many (1:n) matching, such as hedonic exchanges, the role of AI in finding potential matches is certainly extremely interesting. However, I would currently keep AI away from areas where it could directly influence outcomes affecting fairness, orderly markets or transparency.
Standards Sub-Committee Chairperson, Continuous Markets Working Group Co-Chairman, Global Technical Committee Governance Board Founding Member, FIX Trading Community; Sales Director, Aquis Technologies
Some jars are better left sealed for now. The same questions also mark out where not to start – not a verdict that AI will never belong with certain processes, only that they should wait until the firm has the testing, monitoring and governance to support them. Guardrails are often treated as the answer, but a guardrail is only as good as the testing behind it. A confidence threshold or a human sign-off gate can look solid and still miss the cases that matter, and you only find that out by deliberately trying to break it. The Bank of England and FCA’s survey suggests that most firms are not there yet: pre-deployment AI checks are common, but far fewer firms keep checking the solution once it is live.
- The critical path of the trade lifecycle. Order matching, pre-trade risk checks, margin calculation and settlement instructions demand deterministic, explainable and fast behaviour. Errors here are immediate, often irreversible and felt by the whole market. A component that may answer differently each time it is asked does not belong inside them.
- Decisions about people's rights and access. Credit decisions, account restrictions and similar judgements about clients carry fairness and explanation obligations. The EU AI Act classes creditworthiness assessment of individuals as high-risk. That doesn't rule AI out, but it is no place for a first project.
- Unreviewed regulatory output. Drafting a report is a good use case. Filing one without review is not. A wrong number in a supervisory return is visible, but only to the regulator, and only after it is too late.
- Processes no one owns, or whose data no one trusts. AI does not fix a broken process, it runs it faster. If the inputs are inconsistent or the outcome has no owner, the first project is fixing that.
In each case, the problem is not the model, but rather what surrounds it.
Povilas Randis, who advises payments and e-money firms on risk and regulatory compliance, puts the test for choosing a first use case in a single question:
“ “Start where your analysts are drowning, not where your board is dreaming, and test every candidate with one question: if the AI gets it wrong, will we catch it before the supervisor does? That points to processes that are repetitive, clearly described and rich in real historical data, with rules we already have or can write, because there you can test the AI against actual decisions before it touches a live case. Where real data is thin, and you would be relying on synthetic data, building that data becomes the milestone for the next year or two, and decisions that put the licence on the line, such as exiting a customer or filing a suspicious transaction report, wait until the evidence says the AI is ready.
Head of Consulting, Finvisor Fintech Partners
The fisherman's lesson
The fisherman did not refuse to open the jar. He opened it, and then he kept his head. What saved him was neither strength nor luck but a well-chosen question, asked at the right moment, that tested what the Ifrit claimed against what it could actually do.
That is the discipline AI adoption needs. Not less ambition, but better questions asked earlier: will we see the error, can we undo it, can we measure it, is the work right for it and who owns it? Firms that ask them before choosing a use case will have fewer pilots, and more of those pilots will reach production.
The moral of the tale:
start with processes where a mistake would be cheap, visible and measurable, and where someone already owns the result; leave the critical path for later; keep the seal within reach: agree on the guardrails, human sign-off and accountability, monitoring data and limits within which AI is allowed to change.
Next in the series: "Out of the Jar", on why most AI pilots never reach production, and what the ones that do have in common.
References
- A-Team Group and LSEG (2026): Generative and Agentic AI in Financial Markets: From Pilot to Platform, white paper, September.
- Burton, R F (trans.) (1885): The Book of the Thousand Nights and a Night, vol. I.
- Cambridge Centre for Alternative Finance (2026): 2026 Global AI in Financial Services Report: Adoption, Impact and Risks, Cambridge Judge Business School, University of Cambridge, in partnership with the BIS, IMF, World Economic Forum, IDB, CGAP and Arab Monetary Fund, April
- Frost, J, R Kansal, K Rishabh, V Shreeti and L S Y Zhang (2026): "Circular relationships among AI firms", BIS Bulletin, no 137, 1 October.
- Google Cloud (2025): The ROI of AI-assisted Software Development, DORA, September.
- World Quality Report (2025): World Quality Report 2025: Adapting to Emerging Worlds, 17th edition, OpenText, Capgemini and Sogeti, November.
- Bank of England and Financial Conduct Authority (2026): Artificial intelligence in UK financial services – 2026, 26 October.